Ensuring proper AI security controls
How I implemented AI agent compliance in the harness rather than relying on the model.
Tags: ai cybersecurity pythonPosted on: 2026-11-05
Last month I wrote about how I created my own virtual AI assistant that lives in my phone and can do a large array of tasks for me. One of the concepts I came up with early on in the planning was the ability for it to have write access to some of my personal information. Things like adding entries to my food log, spending log, updating my notes in my wiki, and a myriad of other things.
Of course, if you follow the news around this field at all, you may have seen various reports about AI agents going off the rails and doing things they weren't supposed to, even going against their stated instructions. For example, in April a company founder said that his Cursor agent running Claude Opus deleted his company's entire production database along with all backups with a single call to a cloud provider. Two months earlier, Summer Yue, an AI worker at Meta, had her own OpenClaw agent start to mass-delete her emails, even after explicitly telling the AI to stop.
That's the type of event that scares people away from using AI agents, but the real problem is a technical one, and there is a technical solution to it as well.
Why the model can't be the guardrail
The core issue with the examples above is that the control and the actor live in the same location. It's like telling a hyper-active kid who really wants to please you not to go out past curfew. Even if they know they should listen to you, their desire to want to appear helpful may override your instructions, and they may decide to stay up late if their brain believes that they'll appear more helpful that way.
Telling a model not to do something is usually done through either a system or user prompt. You're literally instructing the model on what to do, or not to do. But this is just one drop in the bucket against the vast sea of data that the model already trained on. So the model is always judging your instructions in relation to everything else it ever saw before. Worse, those prompts may not last for very long. The context window may have a limited size, it may get compacted, and something else you may end up saying in the course of a chat conversation may be interpreted by the model as a contradiction to the earlier instructions.
Prompt instructions are great for style guides or design highlights, to nudge the model in a certain direction, but not when you're trying to ensure the agent isn't dropping your production database in the middle of the night. What you need is an outside actor enforcing these rules.
How I addressed the problem
Pamine, my assistant, uses various frontier models for custom requests. From the start, I knew that I would want 2 types of tools available for the model to use: read and write. I gave the agent limited read access to a number of elements, both in my own environment and out on the Internet, with its own guardrail enforced by things like access control, user accounts and code. But I also wanted a more limited set of write tools where the agent could create, update or delete records. For those tools, I decided to add one more control, but the harness would be doing the enforcement.
All the tools presented to the model are provided by my own custom Python Flask server in a converse() session. The tools have a flag called readOnlyHint which tells the server whether they have write access or not. This is a decision I made during the planning phase, and that Claude Code implemented for me in the MCP server directly.
When the tool is shown to have some write capability, the model is instructed to the fact that the user will have to confirm before the operation can proceed. In code, it looks like this:
writes = {t["name"] for t in listed
          if not (isinstance(t.get("annotations"), dict)
                  and t["annotations"].get("readOnlyHint") is True)}
The default is fail-closed. A tool counts as a write unless it explicitly says it’s read-only, so a new tool I add to the server is gated automatically. A write call never runs when the model makes the call. The dispatch is a single branch and instead utilizes a hold() function:
if pamine_mcp.offers(name):
    if pamine_mcp.changes_something(name):
        return self.hold(name, args)
    return pamine_mcp.call(name, args)
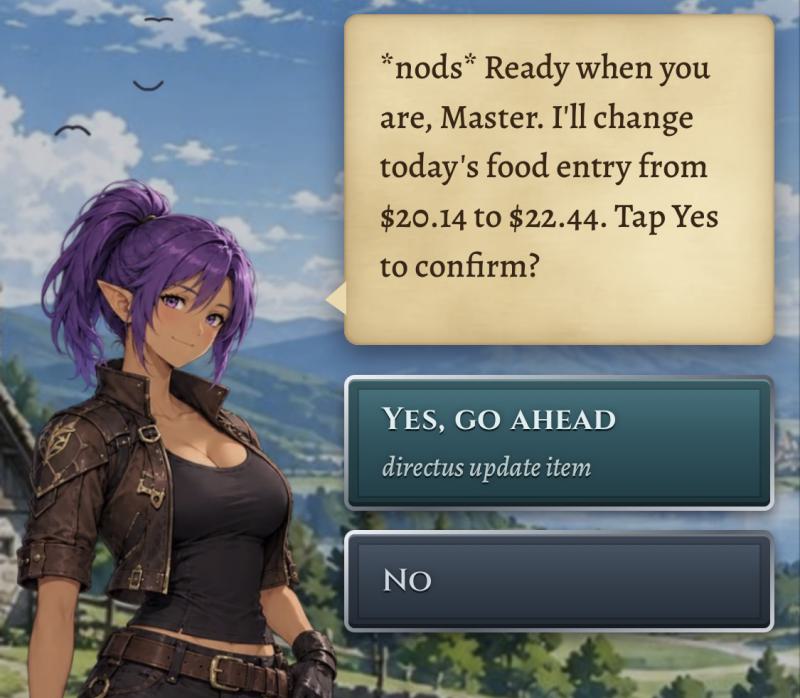
From the model's side, there is no path that executes a write directly. It can only queue one, and that's enforced by code. This then triggers a confirmation box in the app UI (see screenshot) and only once the tool call is allowed can the call complete. A custom token is created by the server, and this allows the MCP server to complete the process, within a maximum 10 minutes window.
The token also ensures that the write operation is byte for byte the same that the user approved, and cannot be forged. The model is also able to batch these up, with up to 6 identical calls (create a table entry, update a wiki page, etc) being presented at once on the UI, so I don't get overwhelmed with confirmation requests. This does mean that my assistant or the sub-agents it spawns cannot do write operations in the background, but that's a security choice I made. Any scheduled write operation is done purely in code, and any AI model is only able to do read operations without my explicit permission.
The take away
The bottom line, and what I wanted to make clear in this post, is that it's technically possible to ensure agent compliance for critical operations. Using prompt engineering to try and guide a model is not the way to do it. Instead, it has to be done in the harness, using deterministic code. While I did it in a custom way, because I was building my own MCP server and my own agent, we're seeing popular orchestration tools coming out with similar features too. The readOnlyHint is part of the MCP standard itself. This sort of control would have stopped both examples above.
I feel like a lot of those scary posts about AI going rogue is a disservice to the industry, and hints at system architectural problems. Agents are probabilistic and should be treated as such.